I am a master’s student in Computer Science and Technology at Harbin Institute of Technology, Shenzhen, under the supervision of Prof. Zhuotao Tian. My research focuses on multimodal large language models and multimodal agents. I expect to graduate in June 2027.
I received dual bachelor’s degrees in mathematics and computer science from Shenzhen University in 2023. Previously, I was a Research Intern at Tencent, researching video generation agents. I am currently studying multimodal generation and reinforcement learning. Meanwhile, I am looking for a job opportunity as a multimodal AI engineer.
🔥 News
- May 2026: ☕️Serving as a reviewer for NeurIPS 2026.
- Feb. 2026: ⭐️Our Paper FlashVID was accepted to ICLR 2026 and selected for an oral presentation.
- Oct. 2025: 🔍Joined the Platform and Content Group (PCG), Tencent for research on video generation agents.
- Sep. 2025: 🍾Our paper DyTok was accepted to NeurIPS 2025.
- Apr. 2024: 📢Received an offer of admission to the master’s program at the School of Computer Science and Technology, Harbin Institute of Technology, Shenzhen.
- Jun. 2023: 🎓Graduated from Shenzhen University with dual degrees in mathematics and computer science.
📝 Publications
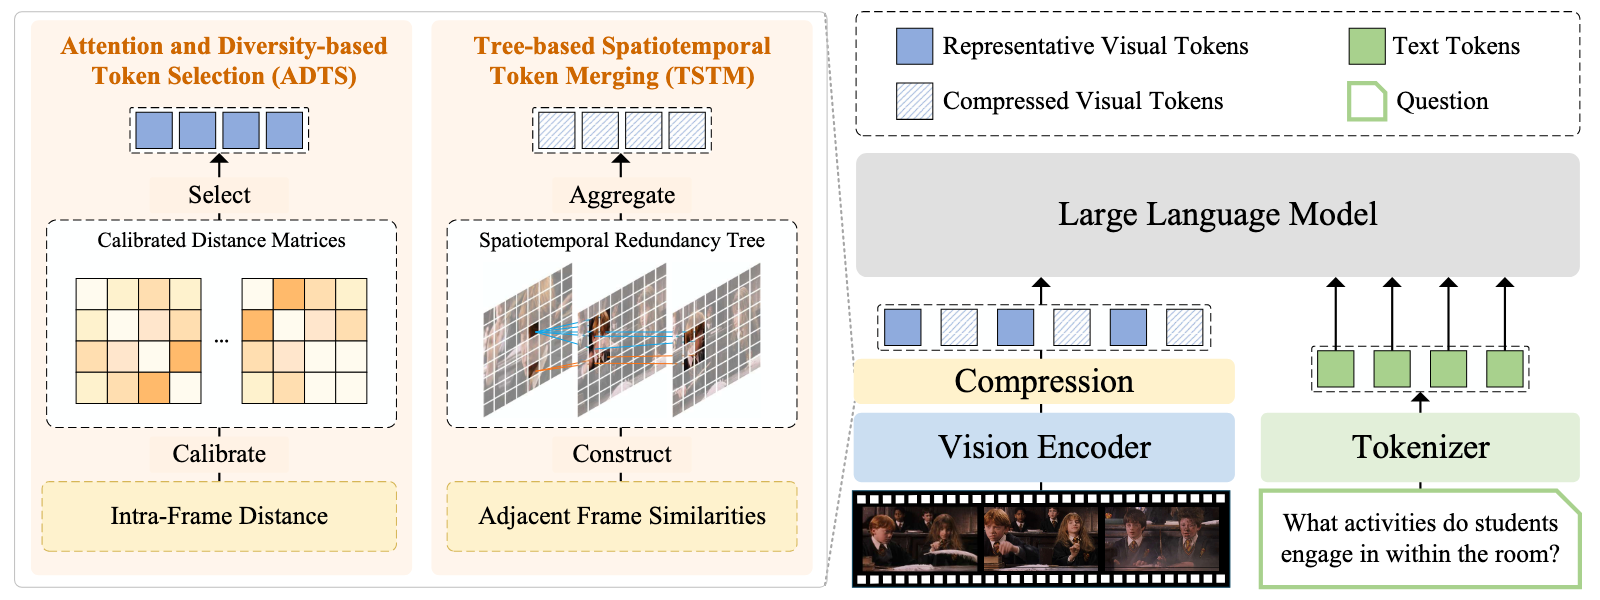
Ziyang Fan, Keyu chen, Ruilong Xing, Yulin Li, Li Jiang, Zhuotao Tian


- FlashVID achieves state-of-the-art performance across three repesentative VLLMs on five widely used video understanding benchmarks.
- FlashVID can serve as a plug-and-play module, enabling a 10x increase in video frame input to Qwen2.5-VL, resulting in a performance improvement of 8.6%.
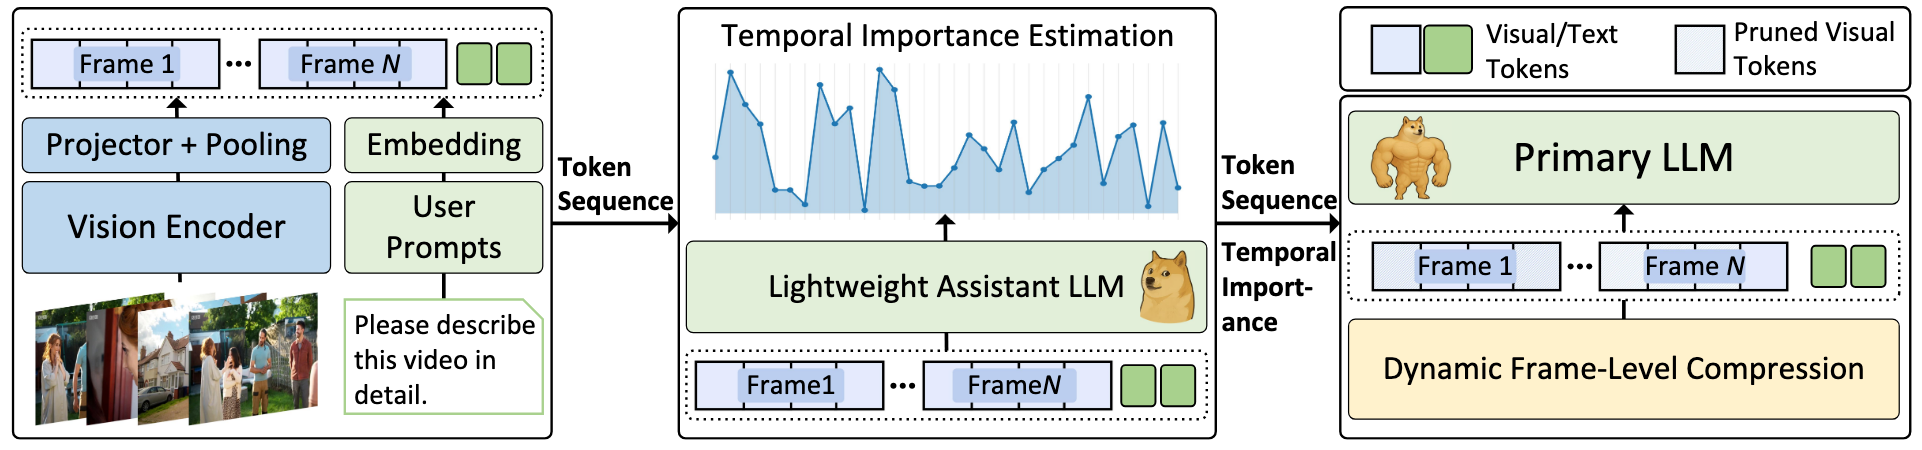
Less Is More, but Where? Dynamic Token Compression via LLM-Guided Keyframe Prior
Yulin Li*, Haokun Gui*, Ziyang Fan, Junjie Wang, Bin Kang, Bin Chen, Zhuotao Tian
* Equal contribution.



- DyTok is a two-stage visual token pruning framework, including two synergistic modules: (1) Temporal Importance Estimation leverages cross-modal attention from a lightweight assistant model to identify keyframes, followed by (2) Dynamic Frame-Level Compression that allocates token budgets proportionally to preserve salient content.
🎖 Honors and Awards
- Feb. 2026: FlashVID was selected for an oral presentation at ICLR 2026.
📖 Education
Master's degree in Computer Science and Technology
Harbin Institute of Technology, Shenzhen
Bachelor's degree in Information and Computing Science
Shenzhen University
💻 Internships
Research Intern, Platform and Content Group (PCG), Tencent
Research on video generation agents.